8
DeepSeek
vllm推理llama3.1 8b instruct问题
2025-04-20 19:25:05
88

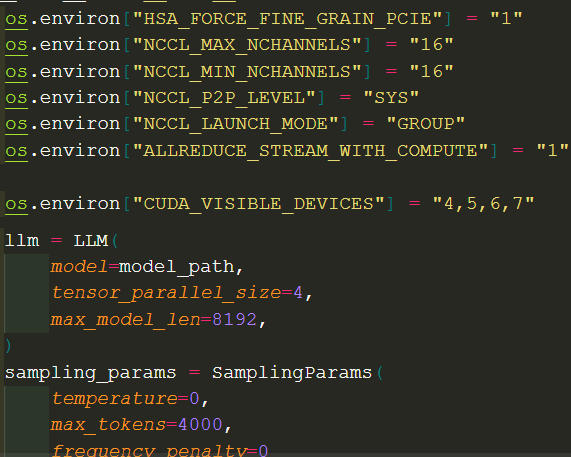
代码如下:
attachmentId-image.png

但是会报错:

怎么解决这个问题,使用的镜像是image.sourcefind.cn:5000/dcu/admin/base/custom:vllm0.7.2-ubuntu22.04-dtk25.04-rc7-das1.5-py3.10-20250327s使用   tensor_parallel_size = 1  又太慢了,或者说有没有其他加速推理的办法

全部评论(6)
只看楼主
W
wangs
1楼

麻烦提供完整测试代码

2025/4/15
网
网友ztfqqG
回复 @wangs

import json

import os

# os.environ["CUDA_DEVICE_ORDER"] = "PCI_BUS_ID"

# os.environ["CUDA_VISIBLE_DEVICES"]="1"

import torch

print("Current visible device count:", torch.cuda.device_count())

for i in range(torch.cuda.device_count()):

print(f"Device {i}: {torch.cuda.get_device_name(i)}")

from vllm import LLM, SamplingParams

from tqdm import tqdm

from prompts import icl_sys_prompt, icl_user_prompt, icl_ass_prompt

if __name__ == "__main__":

os.environ["HSA_FORCE_FINE_GRAIN_PCIE"] = "1"

os.environ["NCCL_MAX_NCHANNELS"] = "16"

os.environ["NCCL_MIN_NCHANNELS"] = "16"

os.environ["NCCL_P2P_LEVEL"] = "SYS"

os.environ["NCCL_LAUNCH_MODE"] = "GROUP"

os.environ["ALLREDUCE_STREAM_WITH_COMPUTE"] = "1"

os.environ["CUDA_VISIBLE_DEVICES"] = "0,1,2,3"

model_path = "/reason/llama/Meta-Llama-3.1-8B-Instruct"

file_path = '/retrieval_result_100.json'

output_file_path = '/reason_result_batch_no_except.json'

with open(file_path, 'r', encoding='utf-8') as f:

retrieval_data = json.load(f)

llm = LLM(

model=model_path,

tensor_parallel_size=1,

max_model_len=8192,

)

sampling_params = SamplingParams(

temperature=0,

max_tokens=4000,

frequency_penalty=0

)

prompts = []

sample_ids = []

processed_data = {}

for sample_id, sample_info in retrieval_data.items():

scored_triples = sample_info.get('scored_triples', [])

triples = []

if scored_triples:

for triple in scored_triples:

h, r, t, score = triple

triples.append((h, r, t))

triples_str = "\n".join([f"({h}, {r}, {t})" for h, r, t in triples])

prompt = f"{icl_sys_prompt}\n\n" + \

"Example Input:\n" + icl_user_prompt + "\n" + \

"Example Output:\n" + icl_ass_prompt + "\n\n" + \

"Current Input:\n" + \

"Triplets:\n" + triples_str + "\n" + \

"Question: " + sample_info['question'] + "\n" + \

"Please provide your answer in the same format as the example.If you cannot get the answer from the provided triples, please answer based on your own knowledge."

prompts.append(prompt)

sample_ids.append(sample_id)

outputs = llm.generate(prompts, sampling_params)

all_natural_language_triples = []

for output in outputs:

text = output.outputs[0].text.strip()

answers = [line.strip() for line in text.split('\n') if line.strip().startswith('ans:')]

all_natural_language_triples.append(answers)

for i, sample_id in enumerate(sample_ids):

processed_data[sample_id] = {

'question': retrieval_data[sample_id].get('question'),

'a_entity': retrieval_data[sample_id].get('a_entity'),

'answers': all_natural_language_triples[i],

}

output_dir = os.path.dirname(output_file_path)

if not os.path.exists(output_dir):

os.makedirs(output_dir, exist_ok=True)

try:

with open(output_file_path, 'w', encoding='utf-8') as f:

json.dump(processed_data, f, ensure_ascii=False, indent=4)

print(f"处理后的数据已保存到 {output_file_path}")

except Exception as e:

print(f"保存处理后的数据时发生错误:{e}")
2025/4/15
网
网友ztfqqG
回复 @wangs

而且就是比如我0号卡在推理,此时我用一号卡推理,即使设置了“# os.environ["CUDA_DEVICE_ORDER"] = "PCI_BUS_ID"

# os.environ["CUDA_VISIBLE_DEVICES"]="1"”这两个也会定位到使用0号卡,这是怎么回事
2025/4/15
W
wangs
回复 @wangs
控制DCU卡的可见性,可以在多卡运行的时候把os.environ["CUDA_VISIBLE_DEVICES"]="0,1,2,3" 修改为os.environ["HIP_VISIBLE_DEVICES"]="0,1,2,3"; 或者加载一下环境变量export HIP_VISIBLE_DEVICES=0,1,2,3 ,实测可以解决报错的问题
2025/4/15
全部5条回复
没有更多内容了
--
楼主
Level.1
0 帖子
楼主热帖
暂无数据

