docker pull image.sourcefind.cn:5000/dcu/admin/base/custom:vllm0.8.5-ubuntu22.04-dtk25.04-rc7-das1.5-py3.10-20250612-fixpy-rocblas0611-rc2麻烦使用该镜像再进行验证下
0
8
0
0
标题
2025-06-16 15:17:49
114
K100-AI 8卡测试DeepSeek-70B模型高并发场景下首token时延和吞吐很慢, 请问有没有优化的方法
vllm 版本0.62
dtk 版本24.03
使用镜像链接:image.sourcefind.cn:5000/dcu/admin/base/pytorch:2.3.0-ubuntu22.04-dtk24.04.3-py3.10
vllm serve 部署命令
vllm serve /home/ubuntu/DeepSeek-R1-Distill-Llama-70B/ --dtype=bfloat16 --trust-remote-code --gpu-memory-utilization 0.9 --max-num-batched-tokens 8096 --disable-log-requests --max-num-seqs 256 --max-model-len 8096 -tp 8 --host 0.0.0.0 --port 9997
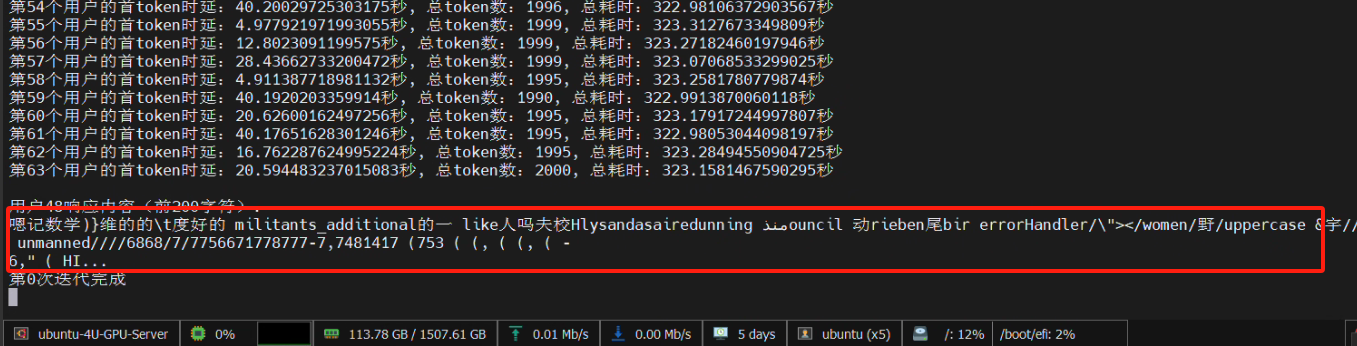
测试64路并发访问 随机会有几路request failed 并且首token时延和吞吐很慢 并且推理结果回复混乱 DS- 32B正常
求助
基础环境
全部评论(4)
只看楼主
P
2025/6/16
网
你docker 启动的命令 是怎样的?
2025/6/16
没有更多内容了
--
楼主

0 点赞
0 帖子
楼主热帖
 暂无数据
常见问题新帖
暂无数据