第一次用海光DCU,想验证一下能不能跑NVIDIA显卡能跑的模型。先说一下环境配置吧。
基本环境信息:
操作系统:Ubuntu 22.04.5 LTS
内核版本:6.8.0-64-generic
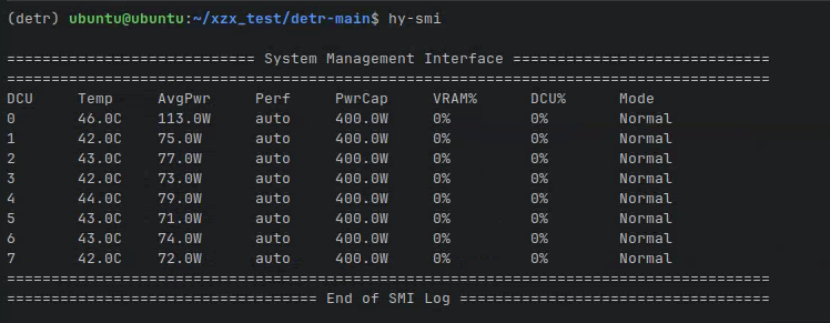
硬件平台:8个海光 DCU
软件环境:
Anaconda 管理虚拟环境(Python 3.8)
torch: torch-2.3.0+das.opt2.dtk24043-cp38-cp38-manylinux_2_28_x86_64.whl
torchvision: torchvision-0.18.1+das.opt1.dtk24043-cp38-cp38-manylinux_2_28_x86_64.whl
DTK 驱动与工具链安装完整 (dtk-24.04.3)
模型运行环境配置完备(HIP_VISIBLE_DEVICES 设置无误)
【所用模型】
用到的是detr模型,用了之前训练好的模型权重,直接在coco验证集上跑推理命令,测试海光DCU情况;
同时也自建了一个建议的resnet模型测试。
【测试情况】
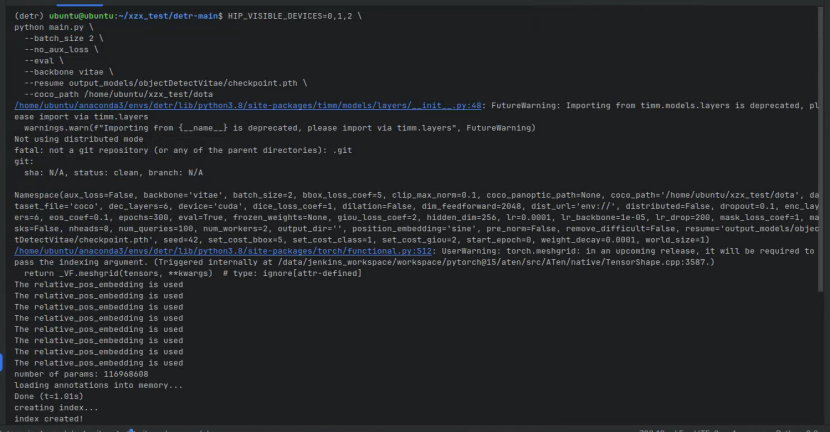
(1)单卡训练
一切正常,detr大模型和resnet都能正常跑。
(2)多卡分布式启动报错
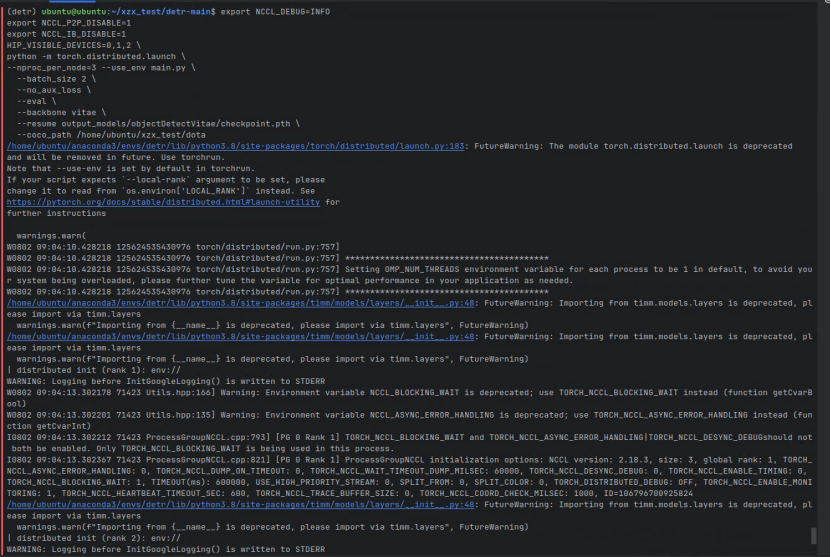
这里试了detr和resnet,都报错,而且报错情况基本一致,说明和模型结构应该没关系。
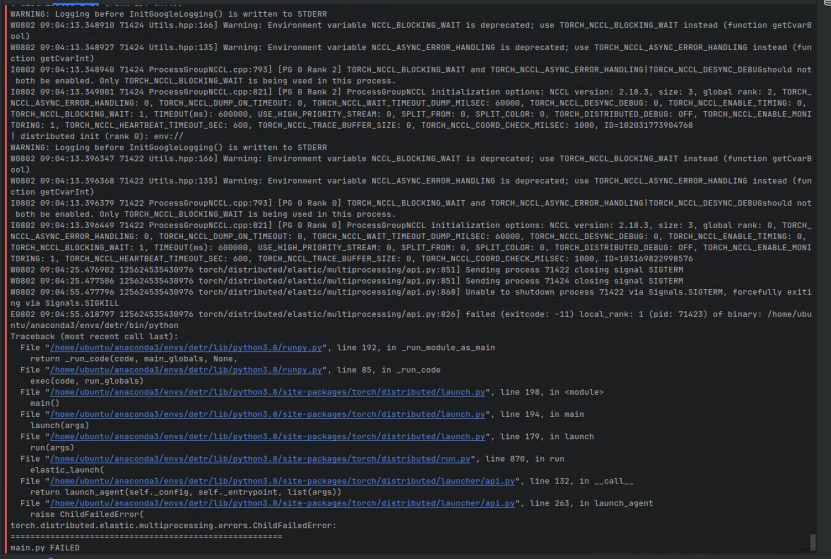
以下是detr报错的情况,如图所示。
'''
启动命令:
export NCCL_DEBUG=INFO #前三行是加的调试信息
export NCCL_P2P_DISABLE=1
export NCCL_IB_DISABLE=1
HIP_VISIBLE_DEVICES=0,1,2 \
python -m torch.distributed.launch \
--nproc_per_node=3 --use_env main.py \
--batch_size 1 \
--no_aux_loss \
--eval \
--backbone vitae \
--resume output_models/objectDetectVitae/checkpoint.pth \
--coco_path /home/ubuntu/xzx_test/dota
'''
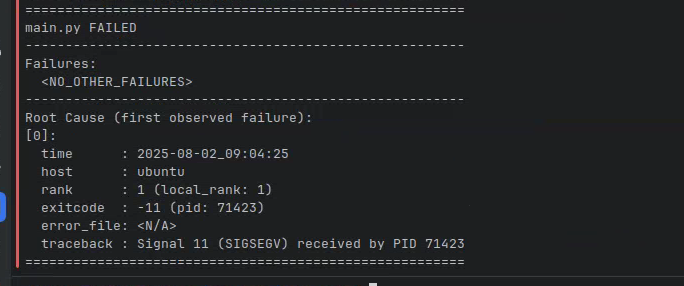
【gpt总结的问题】
通信后端 NCCL 报错
启动命令使用 torchrun 或 torch.distributed.launch 均复现错误
报错栈追踪终止于:
torch.distributed.elastic.multiprocessing.errors.ChildFailedError
Signal 11 (SIGSEGV) received by PID xxxx
exitcode: -11
错误发生在 init_process_group() 后进程刚初始化阶段,尚未进入模型训练逻辑。
所以会是因为PyTorch 分布式 NCCL 多卡通信在海光 DCU 平台上的整体稳定性问题吗 ?:liulei::liulei:
或者是我的torch,torchvision和DTK的版本不兼容 ?:kelian:

 暂无数据 暂无数据
看着像是安装包版本兼容性问题,torch分布式还需要安装apex。推荐使用光源发布的镜像建docker容器进行作业,镜像中dtk和需要的软件包都是齐全的,可以排除版本兼容问题。
docker pull image.sourcefind.cn:5000/dcu/admin/base/pytorch:2.3.0-py3.10-dtk24.04.3-ubuntu20.04