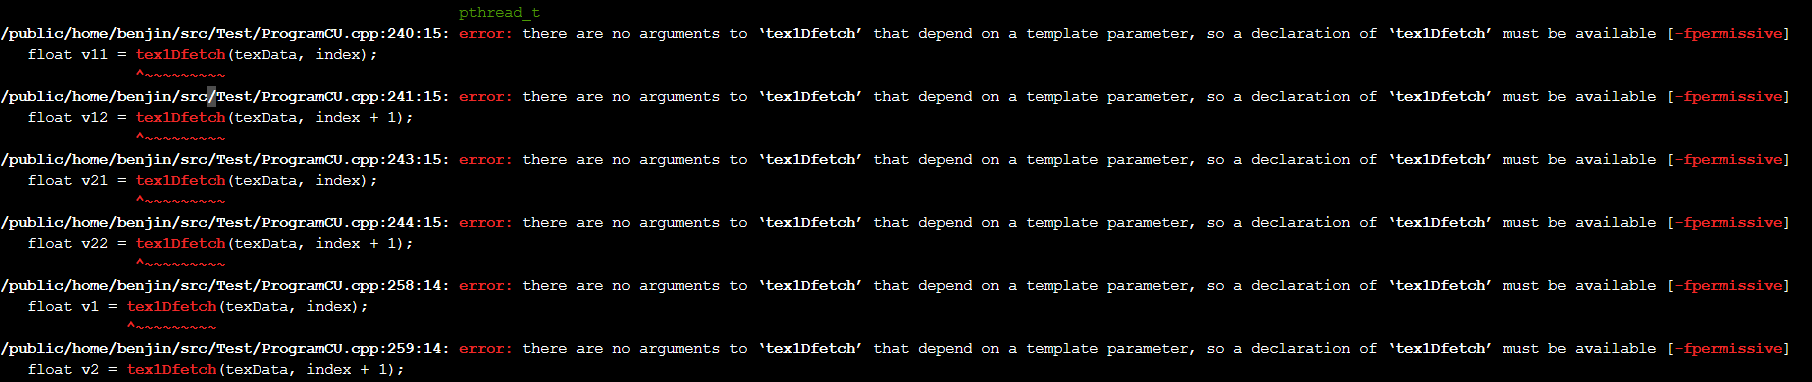
请问大佬为什么说没有申明?hip的其他函数都没问题,说明hip的库已经连接了。
是22.10.1版本,出错的cpp文件源代码如下:
#if defined(CUDA_SIFTGPU_ENABLED)
#define __HIP_PLATFORM_HCC__
#include <iostream>
#include <vector>
#include <algorithm>
#include <math.h>
#include <hip/hip_runtime.h>
#include <hip/hip_runtime_api.h>
#include "GL/glew.h"
#include "stdio.h"
#include "CuTexImage.h"
#include "ProgramCU.h"
#include "GlobalUtil.h"
//----------------------------------------------------------------
//Begin SiftGPU setting section.
//////////////////////////////////////////////////////////
#define IMUL(X,Y) __mul24(X,Y)
//#define FDIV(X,Y) ((X)/(Y))
#define FDIV(X,Y) __fdividef(X,Y)
/////////////////////////////////////////////////////////
//filter kernel width range (don't change this)
#define KERNEL_MAX_WIDTH 33
#define KERNEL_MIN_WIDTH 5
//horizontal filter block size (32, 64, 128, 256, 512)
#define FILTERH_TILE_WIDTH 128
//thread block for vertical filter. FILTERV_BLOCK_WIDTH can be (4, 8 or 16)
#define FILTERV_BLOCK_WIDTH 16
#define FILTERV_BLOCK_HEIGHT 32
//The corresponding image patch for a thread block
#define FILTERV_PIXEL_PER_THREAD 4
#define FILTERV_TILE_WIDTH FILTERV_BLOCK_WIDTH
#define FILTERV_TILE_HEIGHT (FILTERV_PIXEL_PER_THREAD * FILTERV_BLOCK_HEIGHT)
//thread block size for computing Difference of Gaussian
#define DOG_BLOCK_LOG_DIMX 7
#define DOG_BLOCK_LOG_DIMY 0
#define DOG_BLOCK_DIMX (1 << DOG_BLOCK_LOG_DIMX)
#define DOG_BLOCK_DIMY (1 << DOG_BLOCK_LOG_DIMY)
//thread block size for keypoint detection
#define KEY_BLOCK_LOG_DIMX 3
#define KEY_BLOCK_LOG_DIMY 3
#define KEY_BLOCK_DIMX (1<<KEY_BLOCK_LOG_DIMX)
#define KEY_BLOCK_DIMY (1<<KEY_BLOCK_LOG_DIMY)
//#define KEY_OFFSET_ONE
//make KEY_BLOCK_LOG_DIMX 4 will make the write coalesced..
//but it seems uncoalesced writes don't affect the speed
//thread block size for initializing list generation (64, 128, 256, 512 ...)
#define HIST_INIT_WIDTH 128
//thread block size for generating feature list (32, 64, 128, 256, 512, ...)
#define LISTGEN_BLOCK_DIM 128
//how many keypoint orientations to compute in a block
#define ORIENTATION_COMPUTE_PER_BLOCK 64
//how many keypoint descriptor to compute in a block (2, 4, 8, 16, 32)
#define DESCRIPTOR_COMPUTE_PER_BLOCK 4
#define DESCRIPTOR_COMPUTE_BLOCK_SIZE (16 * DESCRIPTOR_COMPUTE_PER_BLOCK)
//how many keypoint descriptor to normalized in a block (32, ...)
#define DESCRIPTOR_NORMALIZ_PER_BLOCK 32
///////////////////////////////////////////
//Thread block size for visualization
//(This doesn't affect the speed of computation)
#define BLOCK_LOG_DIM 4
#define BLOCK_DIM (1 << BLOCK_LOG_DIM)
//End SiftGPU setting section.
__device__ __constant__ float d_kernel[KERNEL_MAX_WIDTH];
texture<float, 1, hipReadModeElementType> texData;
texture<unsigned char, 1, hipReadModeNormalizedFloat> texDataB;
texture<float2, 2, hipReadModeElementType> texDataF2;
texture<float4, 1, hipReadModeElementType> texDataF4;
texture<int4, 1, hipReadModeElementType> texDataI4;
texture<int4, 1, hipReadModeElementType> texDataList;
//template<int i> __device__ float Conv(float *data) { return Conv<i-1>(data) + data[i]*d_kernel[i];}
//template<> __device__ float Conv<0>(float *data) { return data[0] * d_kernel[0]; }
//////////////////////////////////////////////////////////////
template<int FW> __global__ void FilterH( float* d_result, int width)
{
const int HALF_WIDTH = FW >> 1;
const int CACHE_WIDTH = FILTERH_TILE_WIDTH + FW -1;
const int CACHE_COUNT = 2 + (CACHE_WIDTH - 2)/ FILTERH_TILE_WIDTH;
__shared__ float data[CACHE_WIDTH];
const int bcol = IMUL(blockIdx.x, FILTERH_TILE_WIDTH);
const int col = bcol + threadIdx.x;
const int index_min = IMUL(blockIdx.y, width);
const int index_max = index_min + width - 1;
int src_index = index_min + bcol - HALF_WIDTH + threadIdx.x;
int cache_index = threadIdx.x;
float value = 0;
#pragma unroll
for(int j = 0; j < CACHE_COUNT; ++j)
if(cache_index < CACHE_WIDTH)
int fetch_index = src_index < index_min? index_min : (src_index > index_max ? index_max : src_index);
data[cache_index] = tex1Dfetch(texData,fetch_index);
src_index += FILTERH_TILE_WIDTH;
cache_index += FILTERH_TILE_WIDTH;
}
__syncthreads();
if(col >= width) return;
for(int i = 0; i < FW; ++i)
value += (data[threadIdx.x + i]* d_kernel[i]);
// value = Conv<FW-1>(data + threadIdx.x);
d_result[index_min + col] = value;
////////////////////////////////////////////////////////////////////
template<int FW> __global__ void FilterV(float* d_result, int width, int height)
const int CACHE_WIDTH = FW + FILTERV_TILE_HEIGHT - 1;
cmakelist如下
cmake_minimum_required(VERSION 2.8)
add_definitions("-DSIFTGPU_NO_DEVIL")
SET(CUDA_ENABLED TRUE)
# Search for rocm in common locations
#list(APPEND CMAKE_PREFIX_PATH /opt/rocm/hip /opt/rocm)
#find_package(HIP REQUIRED)
#find_package(rocfft REQUIRED)
#include_directories(/opt/rocm/include/)
#find_package(GLEW REQUIRED)
#link_directories( /public/home/benjin/app/OpenGL/lib64 ) # GLEW
set(GLEW_LIBRARIES "/public/home/benjin/app/OpenGL/lib64/libGLEW.a")
include_directories(/public/home/benjin/app/OpenGL/include/)
set(SIFT_GPU_SOURCE_FILES
FrameBufferObject.cpp
FrameBufferObject.h
GlobalUtil.cpp
GlobalUtil.h
GLTexImage.cpp
GLTexImage.h
ProgramGLSL.cpp
ProgramGLSL.h
ProgramGPU.h
PyramidGL.cpp
PyramidGL.h
ShaderMan.cpp
ShaderMan.h
SiftGPU.cpp
SiftGPU.h
SiftMatch.cpp
SiftMatch.h
SiftPyramid.cpp
SiftPyramid.h
)
if(CUDA_ENABLED)
add_definitions("-DCUDA_SIFTGPU_ENABLED")
${SIFT_GPU_SOURCE_FILES}
CuTexImage.cpp
CuTexImage.h
LiteWindow.h
ProgramCU.cpp
ProgramCU.h
PyramidCU.cpp
PyramidCU.h
SiftMatchCU.cpp
SiftMatchCU.h
ADD_LIBRARY(sift_gpu ${SIFT_GPU_SOURCE_FILES})
#else()
# ADD_LIBRARY(sift_gpu ${SIFT_GPU_SOURCE_FILES})
endif()
#target_link_libraries(sift_gpu hip::device)
target_link_libraries(sift_gpu
${SIFT_GPU_LIBRARIES}
${GLEW_LIBRARIES}
${OPENGL_gl_LIBRARY}
${OPENGL_glu_LIBRARY}

 暂无数据 暂无数据 暂无数据 暂无数据