镜像
image.sourcefind.cn:5000/dcu/admin/base/custom:pytorch2.9.1-ubuntu22.04-dtk26.04-0130-py3.10-20260204-qwen3\_5
驱动版本
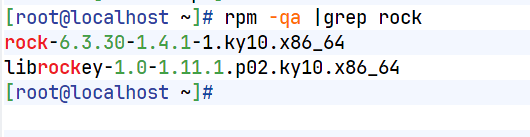
报错信息如下:
HOSTQUEUE <0x557de6081d20>: >>>>>>>> DUMP KERNEL ARGS PTR INFO <<<<<<<<<
HOSTQUEUE <0x557de6081d20>: ptr arg index: 0, ptr: 0x7f07144a0000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7f07144a0000, size byte: 49264
HOSTQUEUE <0x557de6081d20>: ptr arg index: 24, ptr: 0x7effeba00000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7effeba00000, size byte: 201326592
HOSTQUEUE <0x557de6081d20>: ptr arg index: 25, ptr: 0x7efff1400000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7effeba00000, size byte: 201326592
HOSTQUEUE <0x557de6081d20>: ptr arg index: 138, ptr: 0x7f06bea00000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7f06bea00000, size byte: 19776056
HOSTQUEUE <0x557de6081d20>: ptr arg index: 144, ptr: 0x7f03f6bc7400
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7f03f6000000, size byte: 20971520
HOSTQUEUE <0x557de6081d20>: ptr arg index: 145, ptr: 0x7effb8d00000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7effb8800000, size byte: 127926272
HOSTQUEUE <0x557de6081d20>: ptr arg index: 148, ptr: 0x7efebbe00000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7efebbe00000, size byte: 255852544
HOSTQUEUE <0x557de6081d20>: ptr arg index: 149, ptr: 0x7f041cc00000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7f041ca00000, size byte: 20971520
HOSTQUEUE <0x557de6081d20>: ptr arg index: 150, ptr: 0x7eff8a400000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7eff86400000, size byte: 603979776
HOSTQUEUE <0x557de6081d20>: >>>>>>>> DUMP AQL 0x7f117582e000 PACKET WITH INDEX 31398218 <<<<<<<<<
HOSTQUEUE <0x557de6081d20>: >>>>>>>> MATCH KERNEL COMMAND <<<<<<<<<
HOSTQUEUE <0x557de6081d20>: header: 0xb02
HOSTQUEUE <0x557de6081d20>: setup: 3
HOSTQUEUE <0x557de6081d20>: workgroup: x:512, y:1, z:1
HOSTQUEUE <0x557de6081d20>: grid: x:5242880, y:1, z:1
HOSTQUEUE <0x557de6081d20>: group_segment_size: 32
HOSTQUEUE <0x557de6081d20>: private_segment_size: 0
HOSTQUEUE <0x557de6081d20>: completion_signal: 0x0
HOSTQUEUE <0x557de6081d20>: kernel_object: 0x7f06f80c4700
HOSTQUEUE <0x557de6081d20>: device id: 4
HOSTQUEUE <0x557de6081d20>: >>>>>>>> FIND MATCH KERNEL DETAILS <<<<<<<<<
HOSTQUEUE <0x557de6081d20>: kernel name: triton_red_fused__to_copy_add_mean_moe_forward_shared_mul_pow_rsqrt_1
HOSTQUEUE <0x557de6081d20>: >>>>>>>> DUMP KERNEL ARGS: size: 56 <<<<<<<<<
00 00 a0 eb ff 7e 00 00 00 00 e0 bb fe 7e 00 00
00 82 5e 2a 04 7f 00 00 00 00 40 f1 ff 7e 00 00
00 00 20 ee ff 7e 00 00 00 28 00 00 00 08 00 00
00 00 00 00 00 00 00 00
HOSTQUEUE <0x557de6081d20>: >>>>>>>> DUMP KERNEL ARGS PTR INFO <<<<<<<<<
HOSTQUEUE <0x557de6081d20>: ptr arg index: 0, ptr: 0x7effeba00000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7effeba00000, size byte: 201326592
HOSTQUEUE <0x557de6081d20>: ptr arg index: 1, ptr: 0x7efebbe00000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7efebbe00000, size byte: 255852544
HOSTQUEUE <0x557de6081d20>: ptr arg index: 2, ptr: 0x7f042a5e8200
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7f042a400000, size byte: 2097152
HOSTQUEUE <0x557de6081d20>: ptr arg index: 3, ptr: 0x7efff1400000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7effeba00000, size byte: 201326592
HOSTQUEUE <0x557de6081d20>: ptr arg index: 4, ptr: 0x7effee200000
HOSTQUEUE <0x557de6081d20>: origin ptr: 0x7effeba00000, size byte: 201326592
HOSTQUEUE <0x557de6081d20>: >>>>>>>> DUMP AQL 0x7f117582e000 PACKET WITH INDEX 31398219 <<<<<<<<<
HOSTQUEUE <0x557de6081d20>: >>>>>>>> MATCH KERNEL COMMAND <<<<<<<<<
HOSTQUEUE <0x557de6081d20>: header: 0xb02
HOSTQUEUE <0x557de6081d20>: setup: 3
HOSTQUEUE <0x557de6081d20>: workgroup: x:256, y:1, z:1
HOSTQUEUE <0x557de6081d20>: grid: x:512, y:80, z:1
HOSTQUEUE <0x557de6081d20>: group_segment_size: 32768
HOSTQUEUE <0x557de6081d20>: private_segment_size: 0
HOSTQUEUE <0x557de6081d20>: completion_signal: 0x0
HOSTQUEUE <0x557de6081d20>: kernel_object: 0x7eff1df0edc0
HOSTQUEUE <0x557de6081d20>: device id: 4
HOSTQUEUE <0x557de5f9ef90>: base_address 0x7f0018a00000
HOSTQUEUE <0x557de5f9ef90>: hsa queue id 13, stream id 114
HOSTQUEUE <0x557de5f9ef90>: get hsa queue W/R ptr: write index: 0, read index: 0
HOSTQUEUE <0x557de5f9ef90>: all command executed
===========================================================================================
=========> HOSTQUEUE <0x557de6111d00>: VMFault HSA QUEUE ANALYSIS <=========
HOSTQUEUE <0x557de6111d00>: base_address 0x7f06ac600000
HOSTQUEUE <0x557de6111d00>: hsa queue id 5, stream id 40
HOSTQUEUE <0x557de6111d00>: get hsa queue W/R ptr: write index: 120, read index: 120
HOSTQUEUE <0x557de6111d00>: all command executed
===========================================================================================
=========> HOSTQUEUE <0x557de608dae0>: VMFault HSA QUEUE ANALYSIS <=========
HOSTQUEUE <0x557de608dae0>: base_address 0x7f06e5a00000
HOSTQUEUE <0x557de608dae0>: hsa queue id 3, stream id 20
HOSTQUEUE <0x557de608dae0>: get hsa queue W/R ptr: write index: 66, read index: 66
HOSTQUEUE <0x557de608dae0>: all command executed
===========================================================================================
=========> HOSTQUEUE <0x557de5fc4f10>: VMFault HSA QUEUE ANALYSIS <=========
HOSTQUEUE <0x557de5fc4f10>: base_address 0x7f072c400000
HOSTQUEUE <0x557de5fc4f10>: hsa queue id 1, stream id 0
HOSTQUEUE <0x557de5fc4f10>: get hsa queue W/R ptr: write index: 964, read index: 964
HOSTQUEUE <0x557de5fc4f10>: all command executed
>>>>>>>> FOR DEVICE 0x557d8ca02420 <<<<<<
>>>>>>>>
>>>>>>>
>>>>>>
>>>>>
>>>>
>>>
>>
>>>>>>>> FOR DEVICE 0x557d8ca032d0 <<<<<<
>>>>>>>>
>>>>>>>
>>>>>>
>>>>>
>>>>
>>>
>>
>>>>>>>> FOR DEVICE 0x557d8ca04180 <<<<<<
>>>>>>>>
>>>>>>>
>>>>>>
>>>>>
>>>>
>>>
>>
>>>>>>>> KERNEL VMFault Analysis END !!!! <<<<<<
>>>>>>>>
>>>>>>>
>>>>>>
>>>>>
>>>>
>>>
>>
=========> HW QUEUE INFO ANALYSIS <==========
Can't read for directory: /sys/kernel/debug/kfd/process
Please check mount/permission
(APIServer pid=350) INFO 04-15 13:32:28 [loggers.py:257] Engine 000: Avg prompt throughput: 0.0 tokens/s, Avg generation throughput: 0.0 tokens/s, Running: 2 reqs, Waiting: 0 reqs, GPU KV cache usage: 2.0%, Prefix cache hit rate: 0.0%, MM cache hit rate: 0.0%
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:51 [multiproc_executor.py:246] Worker proc VllmWorker-0 died unexpectedly, shutting down executor.
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [dump_input.py:72] Dumping input data for V1
LLM engine (v0.15.1) with config: model='/app/llms/qwen3.5-35B-A3B', speculative_config=None, tokenizer='/app/llms/qwen3.5-35B-A3B', skip_tokenizer_init=False, tokenizer_mode=auto, revision=None, tokenizer_revision=None, trust_remote_code=True, dtype=torch.bfloat16, max_seq_len=262144, download_dir=None, load_format=auto, tensor_parallel_size=8, pipeline_parallel_size=1, data_parallel_size=1, disable_custom_all_reduce=True, quantization=None, enforce_eager=False, enable_return_routed_experts=False, kv_cache_dtype=auto, device_config=cuda, structured_outputs_config=StructuredOutputsConfig(backend='auto', disable_fallback=False, disable_any_whitespace=False, disable_additional_properties=False, reasoning_parser='', reasoning_parser_plugin='', enable_in_reasoning=False), observability_config=ObservabilityConfig(show_hidden_metrics_for_version=None, otlp_traces_endpoint=None, collect_detailed_traces=None, kv_cache_metrics=False, kv_cache_metrics_sample=0.01, cudagraph_metrics=False, enable_layerwise_nvtx_tracing=False, enable_mfu_metrics=False, enable_mm_processor_stats=False, enable_logging_iteration_details=False), seed=0, served_model_name=ZFAI-HY-LLM, enable_prefix_caching=False, enable_chunked_prefill=True, pooler_config=None, compilation_config={'level': None, 'mode': <CompilationMode.VLLM_COMPILE: 3>, 'debug_dump_path': None, 'cache_dir': '', 'compile_cache_save_format': 'binary', 'backend': 'inductor', 'custom_ops': ['none', '+sparse_attn_indexer', '+sparse_attn_indexer'], 'splitting_ops': ['vllm::unified_attention',
'vllm::unified_attention_with_output', 'vllm::unified_mla_attention', 'vllm::unified_mla_attention_with_output', 'vllm::mamba_mixer2', 'vllm::mamba_mixer', 'vllm::short_conv', 'vllm::linear_attention', 'vllm::plamo2_mamba_mixer', 'vllm::gdn_attention_core', 'vllm::kda_attention', 'vllm::sparse_attn_indexer', 'vllm::rocm_aiter_sparse_attn_indexer', 'vllm::unified_kv_cache_update'], 'compile_mm_encoder': False, 'compile_sizes': [], 'compile_ranges_split_points': [10240], 'inductor_compile_config': {'enable_auto_functionalized_v2': False, 'combo_kernels': True, 'benchmark_combo_kernel': True}, 'inductor_passes': {}, 'cudagraph_mode': <CUDAGraphMode.PIECEWISE: 1>, 'cudagraph_num_of_warmups': 1, 'cudagraph_capture_sizes': [1, 2, 4, 8, 16, 24, 32, 40, 48, 56, 64, 72, 80, 88, 96, 104, 112, 120, 128, 136, 144, 152,
160, 168, 176, 184, 192, 200, 208, 216, 224, 232, 240, 248, 256, 272, 288, 304, 320, 336, 352, 368, 384, 400, 416, 432, 448, 464, 480, 496, 512], 'cudagraph_copy_inputs': False, 'cudagraph_specialize_lora': True, 'use_inductor_graph_partition': False, 'pass_config': {'fuse_norm_quant': False, 'fuse_act_quant': False, 'fuse_attn_quant': False, 'eliminate_noops':
True, 'enable_sp': False, 'fuse_gemm_comms': False, 'fuse_allreduce_rms': False}, 'max_cudagraph_capture_size': 512, 'dynamic_shapes_config': {'type': <DynamicShapesType.BACKED: 'backed'>, 'evaluate_guards': False, 'assume_32_bit_indexing': True}, 'local_cache_dir': None,
'static_all_moe_layers': []},
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [dump_input.py:79] Dumping scheduler output for model execution: SchedulerOutput(scheduled_new_reqs=[], scheduled_cached_reqs=CachedRequestData(req_ids=['chatcmpl-8e7edde3d2ec7892-8bdb04df', 'chatcmpl-85c945aadf2ee3ea1c57408dacdaeadf-a4f71a6e'],resumed_req_ids=set(),new_token_ids_lens=[],all_token_ids_lens={},new_block_ids=[None, ([], [], [], [29091, 29092, 29093, 29094, 29095, 29096, 29097, 29098, 29099,
29100, 29101, 29102, 29103, 29104, 29105, 29106, 29107, 29108, 29109, 29110, 29111, 29112,
29113, 29114, 29115, 29116, 29117, 29118, 29119, 29120, 29121, 29122, 29123, 29124, 29125,
29126, 29127, 29128, 29129, 29130, 29131, 29132, 29133, 29134, 29135, 29136, 29137, 29138,
29139, 29140, 29141, 29142, 29143, 29144, 29145, 29146, 29147, 29148, 29149, 29150, 29151,
29152, 29153, 29154, 29155, 29156, 29157, 29158, 29159, 29160, 29161])],num_computed_tokens=[45954, 30718],num_output_tokens=[364, 0]), num_scheduled_tokens={chatcmpl-8e7edde3d2ec7892-8bdb04df: 1, chatcmpl-85c945aadf2ee3ea1c57408dacdaeadf-a4f71a6e: 10239}, total_num_scheduled_tokens=10240, scheduled_spec_decode_tokens={}, scheduled_encoder_inputs={}, num_common_prefix_blocks=[0, 0, 0, 0], finished_req_ids=[], free_encoder_mm_hashes=[], preempted_req_ids=[], has_structured_output_requests=false, pending_structured_output_tokens=false, num_invalid_spec_tokens=null, kv_connector_metadata=null, ec_connector_metadata=null)
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [dump_input.py:81] Dumping scheduler stats: SchedulerStats(num_running_reqs=3, num_waiting_reqs=0, step_counter=0, current_wave=0, kv_cache_usage=0.02266419981498613, prefix_cache_stats=PrefixCacheStats(reset=False, requests=0, queries=0, hits=0, preempted_requests=0, preempted_queries=0, preempted_hits=0), connector_prefix_cache_stats=None, kv_cache_eviction_events=[], spec_decoding_stats=None, kv_connector_stats=None, waiting_lora_adapters={}, running_lora_adapters={}, cudagraph_stats=None, perf_stats=None)
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] EngineCore encountered a fatal
error.
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] Traceback (most recent call last):
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core.py", line 939, in run_engine_core
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] engine_core.run_busy_loop()
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core.py", line 966, in run_busy_loop
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] self._process_engine_step()
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core.py", line 999, in _process_engine_step
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] outputs, model_executed = self.step_fn()
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core.py", line 486, in step_with_batch_queue
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] model_output = future.result()
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/executor/multiproc_executor.py", line 80, in result
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] return super().result()
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/lib/python3.10/concurrent/futures/_base.py", line 451, in result
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] return self.__get_result()
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/lib/python3.10/concurrent/futures/_base.py", line 403, in __get_result
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] raise self._exception
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/executor/multiproc_executor.py", line 84, in wait_for_response
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] response = self.aggregate(get_response())
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/executor/multiproc_executor.py", line 351, in get_response
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] status, result = mq.dequeue(
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/local/lib/python3.10/dist-packages/vllm/distributed/device_communicators/shm_broadcast.py", line 616, in dequeue
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] with self.acquire_read(timeout, cancel, indefinite) as buf:
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/lib/python3.10/contextlib.py", line 135, in __enter__
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] return next(self.gen)
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] File "/usr/local/lib/python3.10/dist-packages/vllm/distributed/device_communicators/shm_broadcast.py", line 531, in acquire_read
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] raise RuntimeError("cancelled")
(EngineCore_DP0 pid=792) ERROR 04-15 13:32:56 [core.py:948] RuntimeError: cancelled
(EngineCore_DP0 pid=792) Process EngineCore_DP0:
(EngineCore_DP0 pid=792) Traceback (most recent call last):
(EngineCore_DP0 pid=792) File "/usr/lib/python3.10/multiprocessing/process.py", line 314, in _bootstrap
(EngineCore_DP0 pid=792) self.run()
(EngineCore_DP0 pid=792) File "/usr/lib/python3.10/multiprocessing/process.py", line 108, in run
(EngineCore_DP0 pid=792) self._target(*self._args, **self._kwargs)
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core.py", line 950, in run_engine_core
(EngineCore_DP0 pid=792) raise e
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core.py", line 939, in run_engine_core
(EngineCore_DP0 pid=792) engine_core.run_busy_loop()
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core.py", line 966, in run_busy_loop
(EngineCore_DP0 pid=792) self._process_engine_step()
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core.py", line 999, in _process_engine_step
(EngineCore_DP0 pid=792) outputs, model_executed = self.step_fn()
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core.py", line 486, in step_with_batch_queue
(EngineCore_DP0 pid=792) model_output = future.result()
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/v1/executor/multiproc_executor.py", line 80, in result
(EngineCore_DP0 pid=792) return super().result()
(EngineCore_DP0 pid=792) File "/usr/lib/python3.10/concurrent/futures/_base.py", line 451, in result
(EngineCore_DP0 pid=792) return self.__get_result()
(EngineCore_DP0 pid=792) File "/usr/lib/python3.10/concurrent/futures/_base.py", line 403, in __get_result
(EngineCore_DP0 pid=792) raise self._exception
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/v1/executor/multiproc_executor.py", line 84, in wait_for_response
(EngineCore_DP0 pid=792) response = self.aggregate(get_response())
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/v1/executor/multiproc_executor.py", line 351, in get_response
(EngineCore_DP0 pid=792) status, result = mq.dequeue(
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/distributed/device_communicators/shm_broadcast.py", line 616, in dequeue
(EngineCore_DP0 pid=792) with self.acquire_read(timeout, cancel, indefinite) as buf:
(EngineCore_DP0 pid=792) File "/usr/lib/python3.10/contextlib.py", line 135, in __enter__
(EngineCore_DP0 pid=792) return next(self.gen)
(EngineCore_DP0 pid=792) File "/usr/local/lib/python3.10/dist-packages/vllm/distributed/device_communicators/shm_broadcast.py", line 531, in acquire_read
(EngineCore_DP0 pid=792) raise RuntimeError("cancelled")
(EngineCore_DP0 pid=792) RuntimeError: cancelled
(APIServer pid=350) ERROR 04-15 13:32:56 [async_llm.py:693] AsyncLLM output_handler failed.
(APIServer pid=350) ERROR 04-15 13:32:56 [async_llm.py:693] Traceback (most recent call last):
(APIServer pid=350) ERROR 04-15 13:32:56 [async_llm.py:693] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/async_llm.py", line 649, in output_handler
(APIServer pid=350) ERROR 04-15 13:32:56 [async_llm.py:693] outputs = await engine_core.get_output_async()
(APIServer pid=350) ERROR 04-15 13:32:56 [async_llm.py:693] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core_client.py", line 894, in get_output_async
(APIServer pid=350) ERROR 04-15 13:32:56 [async_llm.py:693] raise self._format_exception(outputs) from None
(APIServer pid=350) ERROR 04-15 13:32:56 [async_llm.py:693] vllm.v1.engine.exceptions.EngineDeadError: EngineCore encountered an issue. See stack trace (above) for the root cause.
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] Error in chat completion stream
generator.
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] Traceback (most recent call last):
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/entrypoints/openai/chat_completion/serving.py", line 735, in chat_completion_stream_generator
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] async for res in result_generator:
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/async_llm.py", line 572, in generate
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] out = q.get_nowait() or await q.get()
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/output_processor.py", line 80, in get
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] raise output
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/async_llm.py", line 649, in output_handler
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] outputs = await engine_core.get_output_async()
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core_client.py", line 894, in get_output_async
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] raise self._format_exception(outputs) from None
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] vllm.v1.engine.exceptions.EngineDeadError: EngineCore encountered an issue. See stack trace (above) for the root cause.
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] Error in chat completion stream
generator.
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] Traceback (most recent call last):
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/entrypoints/openai/chat_completion/serving.py", line 735, in chat_completion_stream_generator
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] async for res in result_generator:
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/async_llm.py", line 572, in generate
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] out = q.get_nowait() or await q.get()
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/output_processor.py", line 80, in get
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] raise output
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/async_llm.py", line 649, in output_handler
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] outputs = await engine_core.get_output_async()
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] File "/usr/local/lib/python3.10/dist-packages/vllm/v1/engine/core_client.py", line 894, in get_output_async
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] raise self._format_exception(outputs) from None
(APIServer pid=350) ERROR 04-15 13:32:56 [serving.py:1377] vllm.v1.engine.exceptions.EngineDeadError: EngineCore encountered an issue. See stack trace (above) for the root cause.
(APIServer pid=350) WARNING 04-15 13:32:56 [protocol.py:53] The following fields were present in the request but ignored: {'prompt_cache_key'}
(APIServer pid=350) INFO: 121.204.0.90:55489 - "POST /v1/chat/completions HTTP/1.1" 200 OK
(APIServer pid=350) INFO: 121.204.0.90:55491 - "POST /v1/chat/completions HTTP/1.1" 200 OK
(APIServer pid=350) INFO: Shutting down
(APIServer pid=350) INFO: Waiting for application shutdown.
(APIServer pid=350) INFO: Application shutdown complete.
(APIServer pid=350) INFO: Finished server process [350]
root@localhost:/app/llms# /usr/lib/python3.10/multiprocessing/resource_tracker.py:224: UserWarning: resource_tracker: There appear to be 8 leaked semaphore objects to clean up at shutdown

 暂无数据 暂无数据
docker pull harbor.sourcefind.cn:5443/dcu/admin/base/vllm:0.15.1--ubuntu22.04-dtk26.04-py3.10-20260409