Z100L和dtk23.10
0
2
0
0
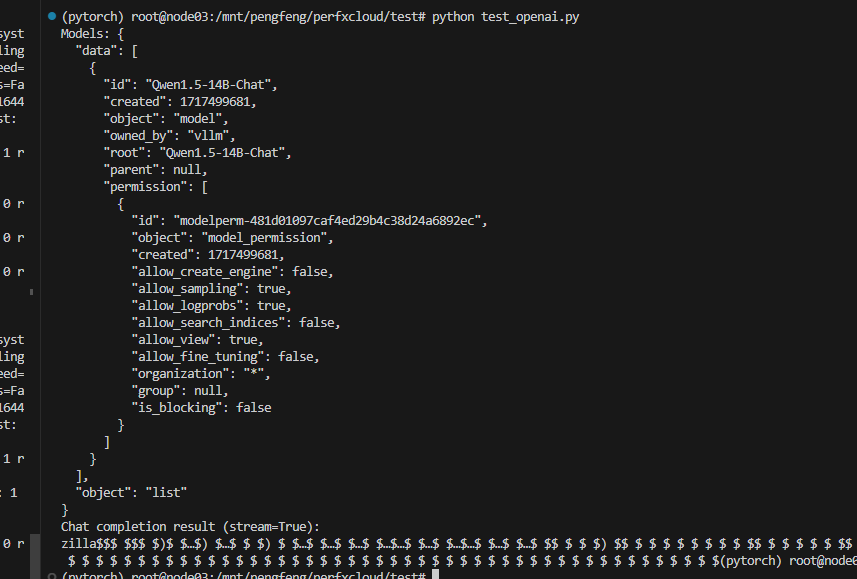
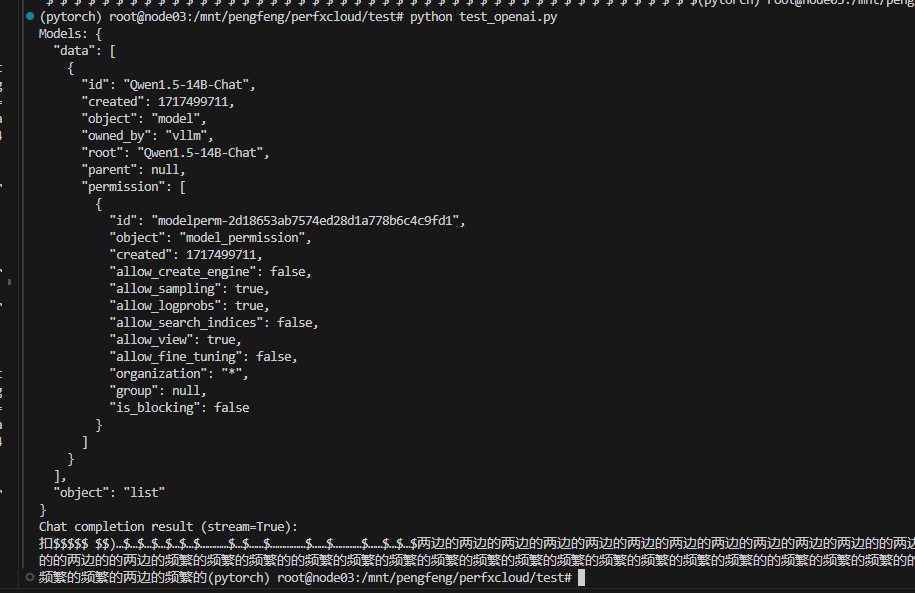
vllm 0.3.3 Qwen1.5可支持部署,但是回答胡言乱语,是代码移植的问题,还是vllm部署模型的时候需要指定特殊的参数配置
2024-06-04 19:15:50
213
使用的是你们封装的vllm 0.3.3 rocm版本
部署qwen1.5 14B和qwen1.5 72b int都是可以的,四卡部署
部署命令: CUDA_VISIBLE_DEVICES='0,1,2,3' python -m vllm.entrypoints.openai.api_server --model Qwen1.5-14B-Chat --enforce-eager --tensor-parallel-size 4 --trust-remote-code --dtype float16 --max-model-len 4096 --max-num-seqs 100 --gpu-memory-utilization 0.95
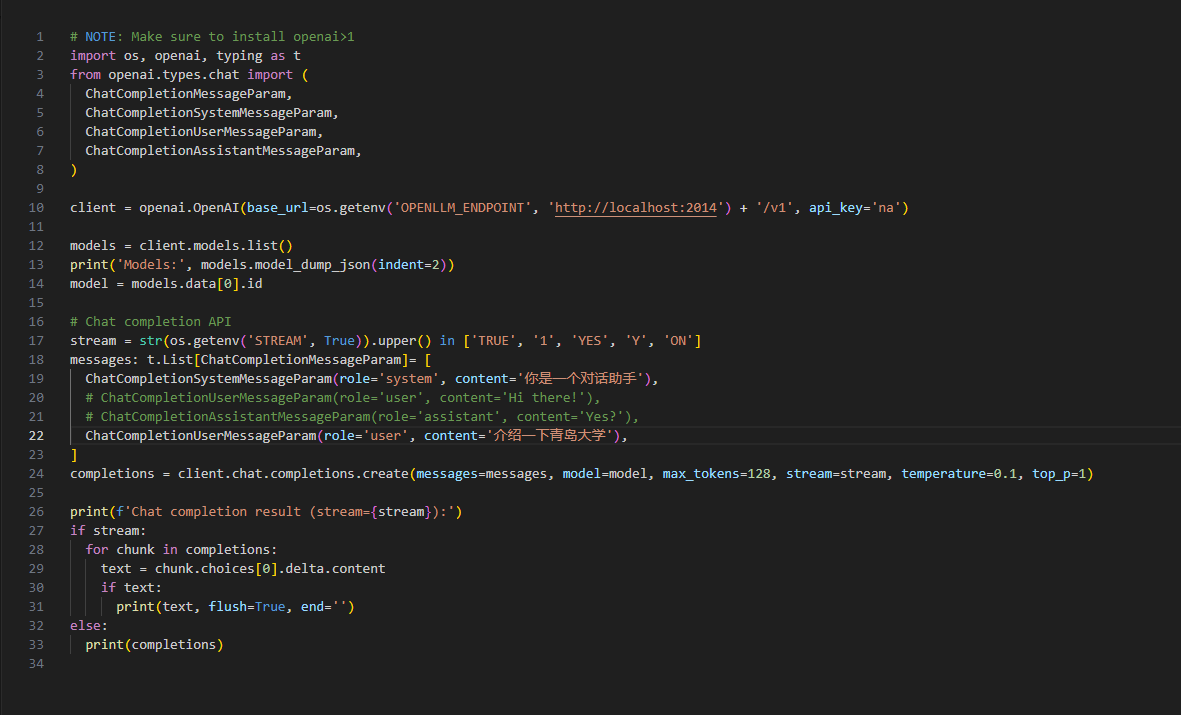
测试脚本
各种乱七八糟的回答:
全部评论(7)
只看楼主
网
2024/6/7
Z
使用的卡和dtk是什么
2024/6/5
没有更多内容了
--
楼主

0 点赞
0 帖子
楼主热帖
 暂无数据
常见问题新帖
暂无数据