使用什么镜像?可以先使用vllm serve起服务测试下能否识别到卡,成功后再使用xinference对齐参数启动服务
0
4
0
0
xinference使用海光HCU安装llama-3.1 时找不到设备怎么处理
2026-02-12 15:22:53
142
DTK/ROCM版本:DTK 25.04.2
xinference版本:v2.0.0.0
pytorch:DAS 1.7
页面启动llama3失败。报找不到设备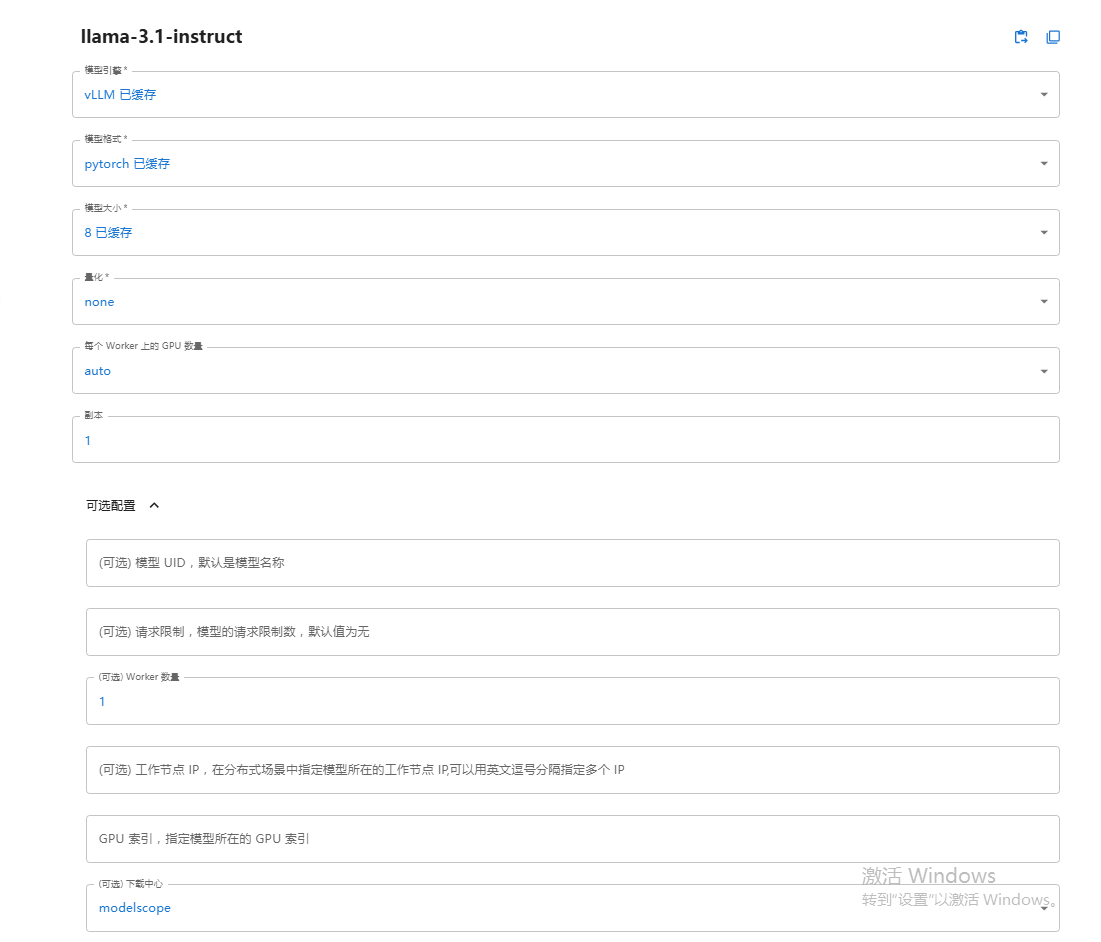
INFO 02-12 07:21:19 [importing.py:44] Triton is installed but 0 active driver(s) found (expected 1). Disabling Triton to prevent runtime errors.
INFO 02-12 07:21:19 [importing.py:68] Triton not installed or not compatible; certain GPU-related functions will not be available.
2026-02-12 07:21:23,179 xinference.core.model 24878 DEBUG Starting ModelActor at 0.0.0.0:41595, uid: b'llama-3.1-instruct-0'
2026-02-12 07:21:23,180 xinference.core.model 24878 INFO Start requests handler.
/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/xinference/model/llm/core.py:209: UserWarning: enable_thinking cannot be disabled for non hybrid model, will be ignored
warnings.warn(
2026-02-12 07:21:23,187 xinference.model.llm.vllm.core 24878 INFO Loading llama-3.1-instruct with following model config: {'tokenizer_mode': 'auto', 'trust_remote_code': True, 'tensor_parallel_size': 0, 'pipeline_parallel_size': 1, 'block_size': 16, 'swap_space': 4, 'gpu_memory_utilization': 0.9, 'max_num_seqs': 256, 'quantization': None, 'max_model_len': None, 'scheduling_policy': 'fcfs'}Enable lora: False. Lora count: 0.
2026-02-12 07:21:23,210 xinference.model.llm.vllm.core 24878 DEBUG vLLM >= 0.11.1 detected, v1 is default, skip setting VLLM_USE_V1
2026-02-12 07:21:23,214 xinference.core.worker 24607 ERROR Failed to load model llama-3.1-instruct-0
Traceback (most recent call last):
File "/opt/xinference-gpu-venv/lib/python3.10/site-packages/xinference/core/worker.py", line 1680, in launch_builtin_model
await model_ref.load()
File "/opt/xinference-gpu-venv/lib/python3.10/site-packages/xoscar/backends/context.py", line 262, in send
return self._process_result_message(result)
File "/opt/xinference-gpu-venv/lib/python3.10/site-packages/xoscar/backends/context.py", line 111, in _process_result_message
raise message.as_instanceof_cause()
File "/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/xoscar/backends/pool.py", line 689, in send
result = await self._run_coro(message.message_id, coro)
File "/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/xoscar/backends/pool.py", line 389, in _run_coro
return await coro
File "/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/xoscar/api.py", line 418, in __on_receive__
return await super().__on_receive__(message) # type: ignore
File "xoscar/core.pyx", line 564, in __on_receive__
raise ex
File "xoscar/core.pyx", line 526, in xoscar.core._BaseActor.__on_receive__
async with self._lock:
File "xoscar/core.pyx", line 527, in xoscar.core._BaseActor.__on_receive__
with debug_async_timeout('actor_lock_timeout',
File "xoscar/core.pyx", line 532, in xoscar.core._BaseActor.__on_receive__
result = await result
File "/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/xinference/core/model.py", line 378, in load
await asyncio.to_thread(self._model.load)
File "/usr/lib/python3.10/asyncio/threads.py", line 25, in to_thread
return await loop.run_in_executor(None, func_call)
File "/usr/lib/python3.10/concurrent/futures/thread.py", line 58, in run
result = self.fn(*self.args, **self.kwargs)
File "/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/xinference/model/llm/vllm/core.py", line 606, in load
self._engine = AsyncLLMEngine.from_engine_args(engine_args)
File "/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/vllm/v1/engine/async_llm.py", line 230, in from_engine_args
vllm_config = engine_args.create_engine_config(usage_context)
File "/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/vllm/engine/arg_utils.py", line 1351, in create_engine_config
device_config = DeviceConfig(device=cast(Device, current_platform.device_type))
File "/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/pydantic/_internal/_dataclasses.py", line 121, in __init__
s.__pydantic_validator__.validate_python(ArgsKwargs(args, kwargs), self_instance=s)
File "/root/.xinference/virtualenv/v4/llama-3.1-instruct/vllm/3.10.12/lib/python3.10/site-packages/vllm/config/device.py", line 75, in __post_init__
self.device = torch.device(self.device_type)
RuntimeError: [address=0.0.0.0:41595, pid=24878] Device string must not be empty
全部评论(2)
只看楼主
P
2/12
没有更多内容了
--
楼主

0 点赞
0 帖子
楼主热帖
 暂无数据
常见问题新帖
暂无数据