加上export VLLM_PCIE_USE_CUSTOM_ALLREDUCE=1这个环境变量试一下
0
1
0
0
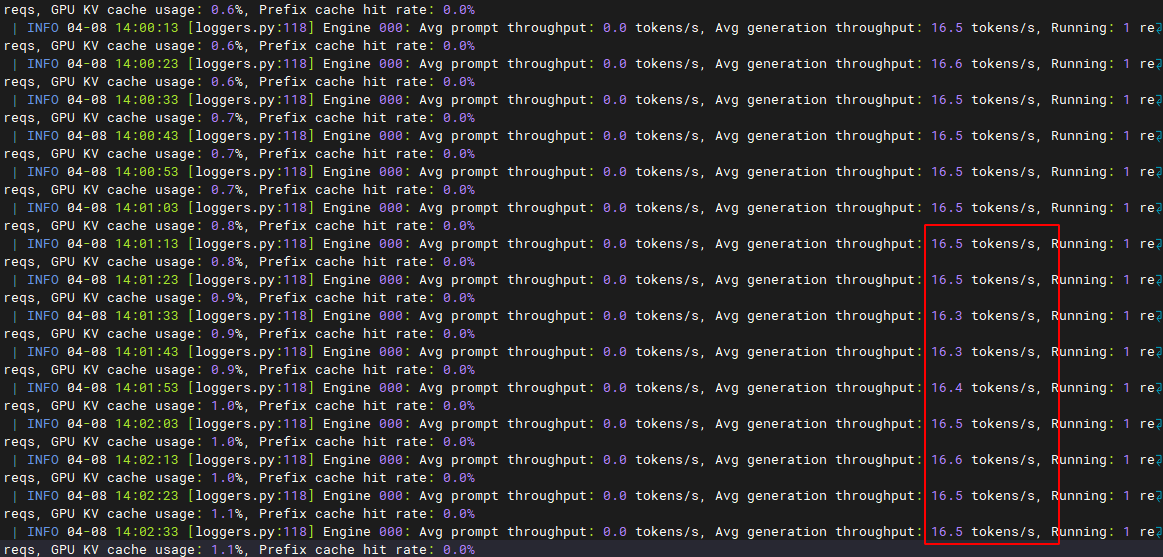
K100AI Qwen3-14B 16.6 tokens/s 这个性能对么,大佬帮看看
2026-04-08 14:24:49
218
1 K100 AI,两张卡,qwen-14B
2 镜像 image.sourcefind.cn:5000/dcu/admin/base/vllm:0.9.2-ubuntu22.04-dtk25.04.2-das1.7-py3.10-20251203
3 启动参数:
non-default args:
{'host': '0.0.0.0', 'port': 8007, 'api_key': 'sk-123456',
'enable_auto_tool_choice': True, 'tool_call_parser': 'hermes',
'model': '/home/model', 'trust_remote_code': True, 'dtype': 'float16',
'max_model_len': 32768, 'enforce_eager': True, 'served_model_name': ['Qwen3-14b'],
'reasoning_parser': 'qwen3',
'tensor_parallel_size': 2,
'block_size': 16,
'gpu_memory_utilization': 0.8,
'swap_space': 32.0,
'enable_prefix_caching': True,
'max_num_batched_tokens': 4096,
'max_num_seqs': 64,
'enable_chunked_prefill': True}
4 如果是简单参数启动 也是15、6token/s,还有优化的空间吗
类似这种
```
vllm serve Qwen/Qwen3-14B \
--port 8001 \
--tensor-parallel-size 2 \
--max-model-len 32768 \
--reasoning-parser qwen3
```
全部评论(2)
只看楼主
Z
4/8
没有更多内容了
--
楼主

0 点赞
0 帖子
楼主热帖
 暂无数据
常见问题新帖
暂无数据