做了如下修改后,目前可以推理速度可以到7 token/s。1.安装最新的驱动6.3.16-V1.1.0a,并根据安装提示升级vbios到6.310.001200r.846907;2.修改系统的ulimit参数* soft nofile 65536 \n* hard nofile 65536 \nroot soft nofile 65536\n root hard nofile 65536;3.在docker-compose.yaml中增加环境变量NCCL_P2P_DISABLE=1。应该是第3点起了作用,供遇到类似问题的人参考。
1
1
0
0
vLLM开启张量并行后速度特别慢
2025-12-28 10:56:41
261
2块K100-AI卡,使用vLLM运行Qwen3-8B模型,配置tensor-parallel-size为2后,生成速度只有0.1 token/s,DCU利用率只有1.7%,麻烦大佬帮忙看看是什么参数配置不正确吗
注:本来是想运行Qwen3-32B模型,配置tensor-parallel-size为2生成速度特别慢,发现运行Qwen3-8B也一样。Qwen3-8B模型配置tensor-parallel-size为1,生成速度大约30 tokens/s。
### 配置
系统:Kylin Linux Advanced Server release V11 (Swan25)
驱动:rock-6.3.15-V1.0.1.run
CPU:Hygon C86 7470 48-core Processor X 2
MEM:64GB X 4
DCU:Hygon K100_AI 64G X 2
hy-smi --showhw
```text
[whkej@localhost models]$ /opt/hyhal/bin/hy-smi --showhw
================================= System Management Interface ==================================
================================================================================================
HCU DID SSID GFX RAS SDMA RAS UMC RAS VBIOS BUS
0 6210 6210 ENABLED ENABLED ENABLED 5.719.001200r.710208 0000:63:00.0
HCU DID SSID GFX RAS SDMA RAS UMC RAS VBIOS BUS
1 6210 6210 ENABLED ENABLED ENABLED 5.719.001200r.710208 0000:a3:00.0
================================================================================================
======================================== End of SMI Log ========================================
```
hy-smi --showproductname
```text
[whkej@localhost models]$ /opt/hyhal/bin/hy-smi --showproductname
================================= System Management Interface ==================================
================================================================================================
HCU[0] : Card Series: K100_AI
HCU[0] : Card Vendor: Chengdu C-3000 IC Design Co., Ltd.
HCU[1] : Card Series: K100_AI
HCU[1] : Card Vendor: Chengdu C-3000 IC Design Co., Ltd.
================================================================================================
======================================== End of SMI Log ========================================
```
hy-smi --showdriverversion
```text
[whkej@localhost models]$ /opt/hyhal/bin/hy-smi --showdriverversion
================================= System Management Interface ==================================
================================================================================================
Driver Version: 6.3.15-V1.0.1
================================================================================================
======================================== End of SMI Log ========================================
```
### 软件信息
镜像:image.sourcefind.cn:5000/dcu/admin/base/vllm:0.9.2-ubuntu22.04-dtk25.04.2-py3.10
模型:Qwen3-8B
docker-compose.yaml
```yaml
services:
vllm:
image: image.sourcefind.cn:5000/dcu/admin/base/vllm:0.9.2-ubuntu22.04-dtk25.04.2-py3.10
container_name: vllm-test
environment:
- HIP_VISIBLE_DEVICES=0,1
command: >
python3 -m vllm.entrypoints.openai.api_server
--model /workspace/models/Qwen3-8B
--tensor-parallel-size 2
--gpu-memory-utilization 0.9
--served-model-name Qwen3-8B
--dtype auto
--max-model-len 32768
--trust-remote-code
--enforce-eager
--host 0.0.0.0
--port 8000
network_mode: host
ipc: host
shm_size: 64G
devices:
- "/dev/kfd:/dev/kfd"
- "/dev/mkfd:/dev/mkfd"
- "/dev/dri:/dev/dri"
volumes:
- /opt/hyhal:/opt/hyhal
- /home/whkej/llm/models:/workspace/models
- /sys/kernel/debug:/sys/kernel/debug
cap_add:
- SYS_PTRACE
security_opt:
- seccomp=unconfined
group_add:
- video
restart: unless-stopped
```
测试命令
```bash
curl -X POST "http://127.0.0.1:8000/v1/completions" \
-H "Content-Type: application/json" \
-d '{
"model": "Qwen3-8B",
"prompt": "Hello, please introduce yourself",
"max_tokens": 50,
"temperature": 0.7
}'
```
vLLM运行日志
```text
[whkej@localhost vllm]$ docker compose logs -f
vllm-test | _ ____ __ __ ___
vllm-test | | | / / / / / / |/ /
vllm-test | | | / / / / / / /|_/ /
vllm-test | | |/ / /___/ /___/ / / /
vllm-test | |___/_____/_____/_/ /_/
vllm-test |
vllm-test | DTK version 25.04.2
vllm-test | vllm version 0.9.2
vllm-test | 2 DCU were detected in the container.
vllm-test | NOTE: Make sure the user is in the 39 group.
vllm-test | For more information, please go to https://developer.hpccube.com/
vllm-test | INFO 12-28 10:43:39 [__init__.py:245] Automatically detected platform rocm.
vllm-test | INFO 12-28 10:43:42 [api_server.py:1395] vLLM API server version 0.9.2
vllm-test | INFO 12-28 10:43:42 [cli_args.py:325] non-default args: {'host': '0.0.0.0', 'model': '/workspace/models/Qwen3-8B', 'trust_remote_code': True, 'max_model_len': 32768, 'enforce_eager': True, 'served_model_name': ['Qwen3-8B'], 'tensor_parallel_size': 2}
vllm-test | INFO 12-28 10:43:52 [config.py:850] This model supports multiple tasks: {'reward', 'embed', 'generate', 'classify'}. Defaulting to 'generate'.
vllm-test | `torch_dtype` is deprecated! Use `dtype` instead!
vllm-test | INFO 12-28 10:43:52 [config.py:1488] Using max model len 32768
vllm-test | INFO 12-28 10:43:52 [config.py:2301] Chunked prefill is enabled with max_num_batched_tokens=2048.
vllm-test | WARNING 12-28 10:43:52 [rocm.py:358] To see benefits of async output processing, enable CUDA graph. Since, enforce-eager is enabled, async output processor cannot be used
vllm-test | INFO 12-28 10:43:58 [__init__.py:245] Automatically detected platform rocm.
vllm-test | INFO 12-28 10:44:00 [core.py:529] Waiting for init message from front-end.
vllm-test | INFO 12-28 10:44:00 [core.py:71] Initializing a V1 LLM engine (v0.9.2) with config: model='/workspace/models/Qwen3-8B', speculative_config=None, tokenizer='/workspace/models/Qwen3-8B', skip_tokenizer_init=False, tokenizer_mode=auto, revision=None, override_neuron_config={}, tokenizer_revision=None, trust_remote_code=True, dtype=torch.bfloat16, max_seq_len=32768, download_dir=None, load_format=auto, tensor_parallel_size=2, pipeline_parallel_size=1, disable_custom_all_reduce=False, quantization=None, enforce_eager=True, kv_cache_dtype=auto, device_config=cuda, decoding_config=DecodingConfig(backend='auto', disable_fallback=False, disable_any_whitespace=False, disable_additional_properties=False, reasoning_backend=''), observability_config=ObservabilityConfig(show_hidden_metrics_for_version=None, otlp_traces_endpoint=None, collect_detailed_traces=None), seed=0, served_model_name=Qwen3-8B, num_scheduler_steps=1, multi_step_stream_outputs=True, enable_prefix_caching=True, chunked_prefill_enabled=True, use_async_output_proc=False, pooler_config=None, compilation_config={"level":0,"debug_dump_path":"","cache_dir":"","backend":"","custom_ops":[],"splitting_ops":[],"use_inductor":true,"compile_sizes":[],"inductor_compile_config":{},"inductor_passes":{},"use_cudagraph":true,"cudagraph_num_of_warmups":0,"cudagraph_capture_sizes":[],"cudagraph_copy_inputs":false,"full_cuda_graph":false,"max_capture_size":0,"local_cache_dir":null}
vllm-test | WARNING 12-28 10:44:00 [multiproc_worker_utils.py:307] Reducing Torch parallelism from 96 threads to 1 to avoid unnecessary CPU contention. Set OMP_NUM_THREADS in the external environment to tune this value as needed.
vllm-test | INFO 12-28 10:44:00 [shm_broadcast.py:289] vLLM message queue communication handle: Handle(local_reader_ranks=[0, 1], buffer_handle=(2, 16777216, 10, 'psm_2bc23870'), local_subscribe_addr='ipc:///tmp/8d3b01da-c213-4f39-b860-01ac76eeb544', remote_subscribe_addr=None, remote_addr_ipv6=False)
vllm-test | INFO 12-28 10:44:05 [__init__.py:245] Automatically detected platform rocm.
vllm-test | INFO 12-28 10:44:05 [__init__.py:245] Automatically detected platform rocm.
vllm-test | WARNING 12-28 10:44:08 [worker_base.py:42] VLLM_RANK1_NUMA is unset or set incorrectly, vllm will not bind to numa! VLLM_RANK1_NUMA = -1
vllm-test | INFO 12-28 10:44:08 [worker_base.py:654] ########## 697 process(rank1) is running on CPU(s): {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16, 17, 18, 19, 20, 21, 22, 23, 24, 25, 26, 27, 28, 29, 30, 31, 32, 33, 34, 35, 36, 37, 38, 39, 40, 41, 42, 43, 44, 45, 46, 47, 48, 49, 50, 51, 52, 53, 54, 55, 56, 57, 58, 59, 60, 61, 62, 63, 64, 65, 66, 67, 68, 69, 70, 71, 72, 73, 74, 75, 76, 77, 78, 79, 80, 81, 82, 83, 84, 85, 86, 87, 88, 89, 90, 91, 92, 93, 94, 95, 96, 97, 98, 99, 100, 101, 102, 103, 104, 105, 106, 107, 108, 109, 110, 111, 112, 113, 114, 115, 116, 117, 118, 119, 120, 121, 122, 123, 124, 125, 126, 127, 128, 129, 130, 131, 132, 133, 134, 135, 136, 137, 138, 139, 140, 141, 142, 143, 144, 145, 146, 147, 148, 149, 150, 151, 152, 153, 154, 155, 156, 157, 158, 159, 160, 161, 162, 163, 164, 165, 166, 167, 168, 169, 170, 171, 172, 173, 174, 175, 176, 177, 178, 179, 180, 181, 182, 183, 184, 185, 186, 187, 188, 189, 190, 191}
vllm-test | INFO 12-28 10:44:08 [worker_base.py:655] ########## 697 process(rank1) is running on memnode(s): {0, 4}
vllm-test | WARNING 12-28 10:44:08 [worker_base.py:42] VLLM_RANK0_NUMA is unset or set incorrectly, vllm will not bind to numa! VLLM_RANK0_NUMA = -1
vllm-test | INFO 12-28 10:44:08 [worker_base.py:654] ########## 696 process(rank0) is running on CPU(s): {0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16, 17, 18, 19, 20, 21, 22, 23, 24, 25, 26, 27, 28, 29, 30, 31, 32, 33, 34, 35, 36, 37, 38, 39, 40, 41, 42, 43, 44, 45, 46, 47, 48, 49, 50, 51, 52, 53, 54, 55, 56, 57, 58, 59, 60, 61, 62, 63, 64, 65, 66, 67, 68, 69, 70, 71, 72, 73, 74, 75, 76, 77, 78, 79, 80, 81, 82, 83, 84, 85, 86, 87, 88, 89, 90, 91, 92, 93, 94, 95, 96, 97, 98, 99, 100, 101, 102, 103, 104, 105, 106, 107, 108, 109, 110, 111, 112, 113, 114, 115, 116, 117, 118, 119, 120, 121, 122, 123, 124, 125, 126, 127, 128, 129, 130, 131, 132, 133, 134, 135, 136, 137, 138, 139, 140, 141, 142, 143, 144, 145, 146, 147, 148, 149, 150, 151, 152, 153, 154, 155, 156, 157, 158, 159, 160, 161, 162, 163, 164, 165, 166, 167, 168, 169, 170, 171, 172, 173, 174, 175, 176, 177, 178, 179, 180, 181, 182, 183, 184, 185, 186, 187, 188, 189, 190, 191}
vllm-test | INFO 12-28 10:44:08 [worker_base.py:655] ########## 696 process(rank0) is running on memnode(s): {0, 4}
vllm-test | (VllmWorker rank=1 pid=697) INFO 12-28 10:44:08 [shm_broadcast.py:289] vLLM message queue communication handle: Handle(local_reader_ranks=[0], buffer_handle=(1, 10485760, 10, 'psm_8c0cfe64'), local_subscribe_addr='ipc:///tmp/ea7d80b5-2ae9-4dba-ba04-442a8fb66d98', remote_subscribe_addr=None, remote_addr_ipv6=False)
vllm-test | (VllmWorker rank=0 pid=696) INFO 12-28 10:44:08 [shm_broadcast.py:289] vLLM message queue communication handle: Handle(local_reader_ranks=[0], buffer_handle=(1, 10485760, 10, 'psm_713412e6'), local_subscribe_addr='ipc:///tmp/1af32853-eb43-4c7f-ae5e-753f6ea4bff3', remote_subscribe_addr=None, remote_addr_ipv6=False)
vllm-test | (VllmWorker rank=0 pid=696) INFO 12-28 10:44:08 [__init__.py:1171] Found nccl from library librccl.so.1
vllm-test | (VllmWorker rank=1 pid=697) INFO 12-28 10:44:08 [__init__.py:1171] Found nccl from library librccl.so.1
vllm-test | (VllmWorker rank=0 pid=696) INFO 12-28 10:44:08 [pynccl.py:70] vLLM is using nccl==2.22.3
vllm-test | (VllmWorker rank=1 pid=697) INFO 12-28 10:44:08 [pynccl.py:70] vLLM is using nccl==2.22.3
vllm-test | (VllmWorker rank=1 pid=697) WARNING 12-28 10:44:09 [custom_all_reduce.py:146] Custom allreduce is disabled because it's not supported on more than two PCIe-only GPUs. To silence this warning, specify disable_custom_all_reduce=True explicitly.
vllm-test | (VllmWorker rank=0 pid=696) WARNING 12-28 10:44:09 [custom_all_reduce.py:146] Custom allreduce is disabled because it's not supported on more than two PCIe-only GPUs. To silence this warning, specify disable_custom_all_reduce=True explicitly.
vllm-test | (VllmWorker rank=0 pid=696) INFO 12-28 10:44:09 [shm_broadcast.py:289] vLLM message queue communication handle: Handle(local_reader_ranks=[1], buffer_handle=(1, 4194304, 6, 'psm_be253f57'), local_subscribe_addr='ipc:///tmp/17c3c06e-a9ba-4d0a-a628-c71446862ef4', remote_subscribe_addr=None, remote_addr_ipv6=False)
vllm-test | (VllmWorker rank=0 pid=696) INFO 12-28 10:44:09 [parallel_state.py:1077] rank 0 in world size 2 is assigned as DP rank 0, PP rank 0, TP rank 0, EP rank 0
vllm-test | (VllmWorker rank=1 pid=697) INFO 12-28 10:44:09 [parallel_state.py:1077] rank 1 in world size 2 is assigned as DP rank 0, PP rank 0, TP rank 1, EP rank 1
vllm-test | (VllmWorker rank=1 pid=697) INFO 12-28 10:44:09 [gpu_model_runner.py:1819] Starting to load model /workspace/models/Qwen3-8B...
vllm-test | (VllmWorker rank=0 pid=696) INFO 12-28 10:44:09 [gpu_model_runner.py:1819] Starting to load model /workspace/models/Qwen3-8B...
vllm-test | (VllmWorker rank=1 pid=697) INFO 12-28 10:44:10 [gpu_model_runner.py:1824] Loading model from scratch...
vllm-test | (VllmWorker rank=0 pid=696) INFO 12-28 10:44:10 [gpu_model_runner.py:1824] Loading model from scratch...
vllm-test | (VllmWorker rank=1 pid=697) INFO 12-28 10:44:10 [rocm.py:288] Using Flash Attention backend on V1 engine. (only supports block size 64)
vllm-test | (VllmWorker rank=0 pid=696) INFO 12-28 10:44:10 [rocm.py:288] Using Flash Attention backend on V1 engine. (only supports block size 64)
Loading safetensors checkpoint shards: 0% Completed | 0/5 [00:00
全部评论(2)
只看楼主
凌
2025/12/31
凌
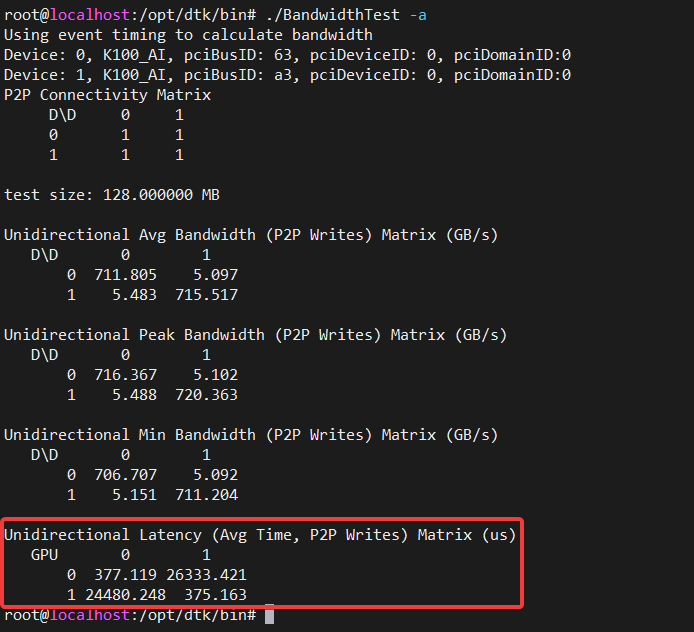
使用DTK自带的BandWidthTest测试工具测试带宽,发现时延比较高,不知道速度慢跟这是否有关系
2025/12/29
没有更多内容了
--
楼主

0 点赞
0 帖子
楼主热帖
 暂无数据
常见问题新帖
暂无数据